Tools
 Tools
Is GPT-6.1 Sol Free? Running Coding Agents on It Without an API Key
GPT-6.1 Sol is not free. The cheapest way to run coding agents on it is a ChatGPT plan in Codex. Here's how to budget several agents on one plan.
Ashley Innocent
October 2, 2026
 Tools
What It Actually Costs to Run an Agent Crew on Free and Cheap Tiers
Which models a Crew can run for free after the 2026-09-22 launches, why a free desktop entitlement is not an API key, and what the cheap API path really costs per week.
Ashley Innocent
September 23, 2026
 Tools
GPT-6 Luna for the Boring 80 Percent: What to Hand a Cheap Runtime
GPT-6 Luna costs $0.10 per million input tokens and $0.50 per million output. Which triage, labelling, first-pass review and test scaffolding belongs on a cheap runtime, and which does not.
Lucas Hayes
September 23, 2026
 Tools
GPT-6 Sol at $0.27 a Task: What Your Fixed Agent Budget Now Buys
OpenAI put GPT-6 Sol at $0.27 per AutomationBench task against Claude Opus 5 at 11.1x that. What a fixed monthly agent budget now buys, and why the new ceiling is your reviewers.
Mia Parker
September 23, 2026
 Tools
Claude Opus 5.5 vs GPT-6 Sol: Choosing Your Crew's Default Runtime
Claude Opus 5.5 and GPT-6 Sol shipped the same day. Compare them on cost per completed task, how long they hold a task, and what they do when stuck, and note OpenAI benchmarked Sol against Opus 5.
Leo Harrison
September 23, 2026
 Tools
When a Cheaper Model Costs More: Price Agent Runs Per Accepted Change
GPT-6 Luna at $0.10 per million tokens lowers the price of an attempt and raises attempts, output and decisions per shipped change. Price agent runs per accepted change, not per token.
Mia Parker
September 23, 2026
 Tools
Is Kie.ai Legit? A Developer's Read on the One-Key Aggregator
What Kie.ai is, who runs it, what the reseller model does and does not guarantee, and the specific risks worth pricing in before you build on it.
Leo Harrison
September 22, 2026
 Tools
Higgsfield Without the Subscription: What You Save and What You Give Up
An even-handed look at what a Higgsfield subscription buys, what the pay-as-you-go route costs instead, and which workflows genuinely need the subscription.
Ryan Mitchell
September 22, 2026
 Tools
How to Review AI-Generated Code With Task-Level Evidence
Review AI-generated code at the task level, not the diff. Learn the roles, statuses, and review gates that let agents produce and verify while humans accept.
Ryan Mitchell
September 20, 2026
 Tools
Coding Agent Cost Management: Tracking Spend Across Claude Code, Codex and Gemini
Running Claude Code, Codex and Gemini side by side scatters your spend across three bills. Here's how to attribute coding agent cost per task, the levers you control, and a decision table by team size.
Aiden Flux
September 20, 2026
 Tools
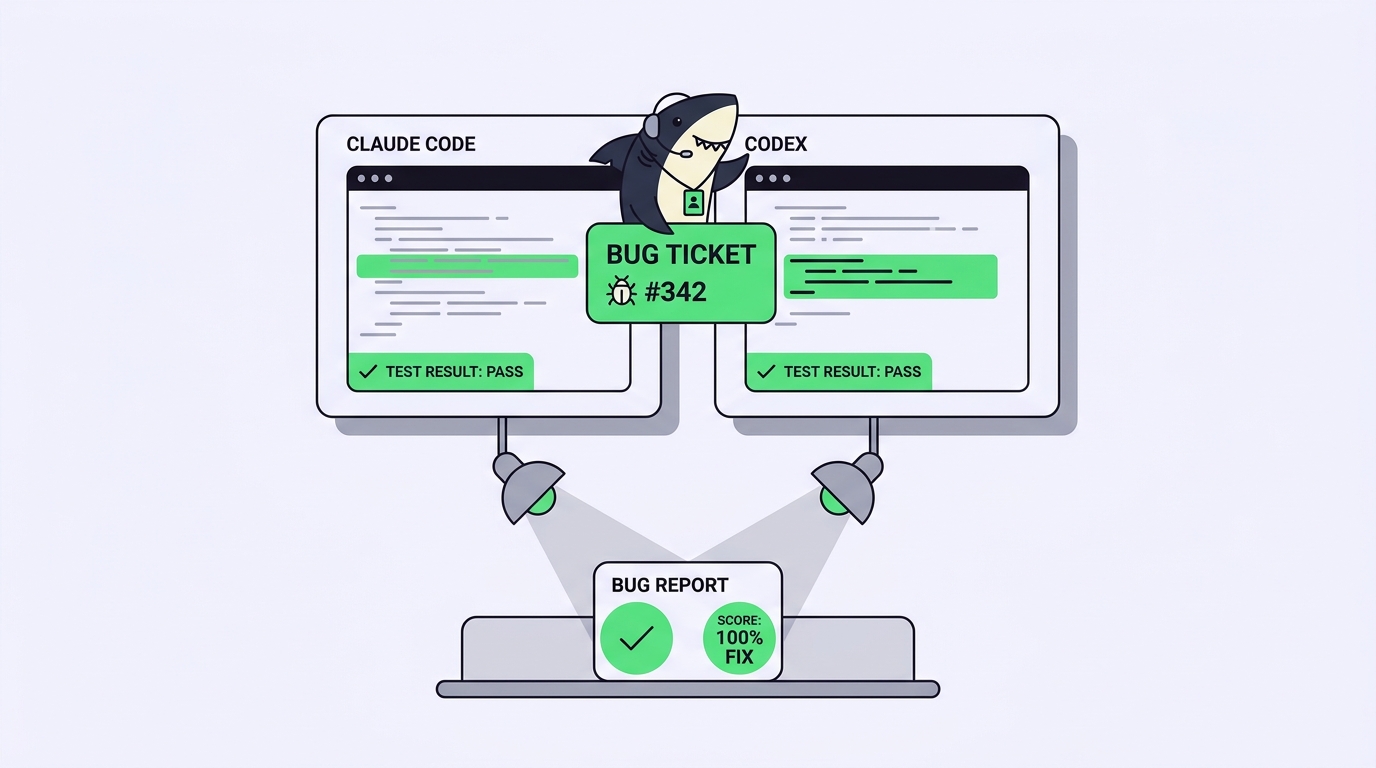
Claude Code vs Codex on the same bug: an honest comparison method
Benchmarks don't tell you whether Claude Code or Codex will fix your bug. Here's an honest method to run both on the same defect, a scoring rubric, and where each wins.
Lucas Hayes
September 20, 2026
 Tools
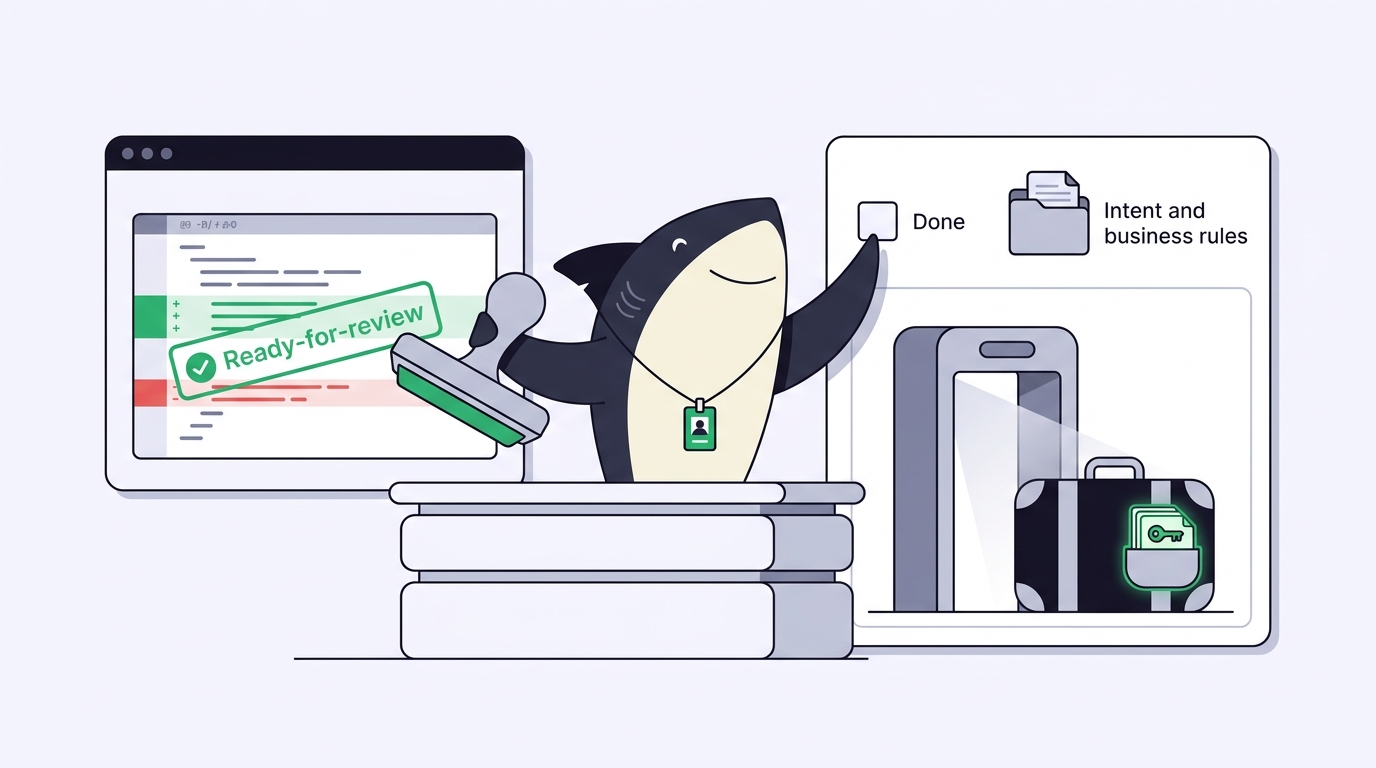
AI Code Review Agents: What They Can and Cannot Verify
AI code review agents verify mechanical, diff-local bugs well and stay blind to intent, business rules, and cross-system behavior. Here's the operating model that covers the gap.
Sophia Carter
September 20, 2026
 Tools
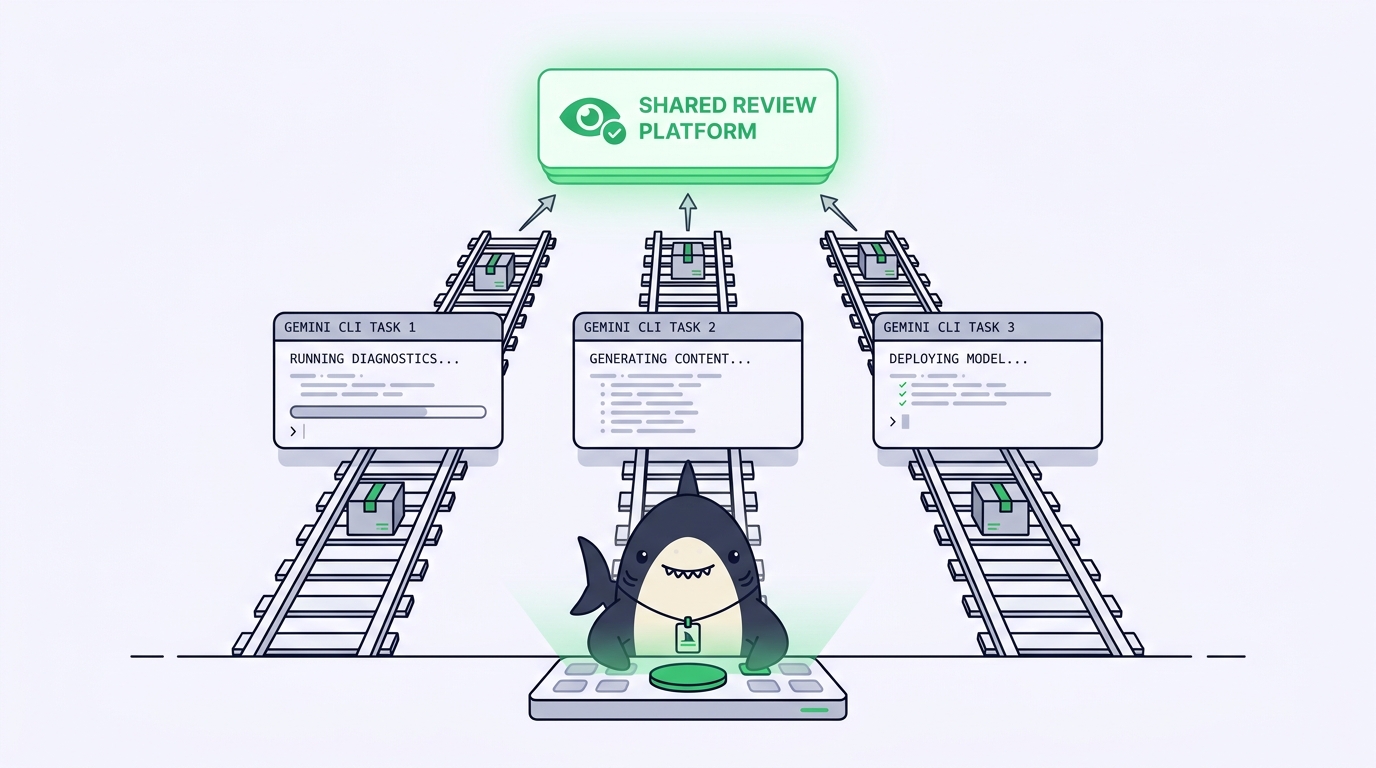
Gemini CLI Parallel Agents: Running Several Gemini Tasks Side by Side
Run several Gemini CLI tasks side by side without collisions. Step-by-step worktree setup, the failure mode at each step, and where a task board takes over.
Mia Parker
September 20, 2026
 Tools
Jev for code review: ranking the pull requests your coding agents open
Use Jev, TypeSafe AI's decision model, to rank the PRs your coding agents open: three typed questions, threshold bands, and a merge that stays with a person.
Sophia Carter
September 18, 2026
 Tools
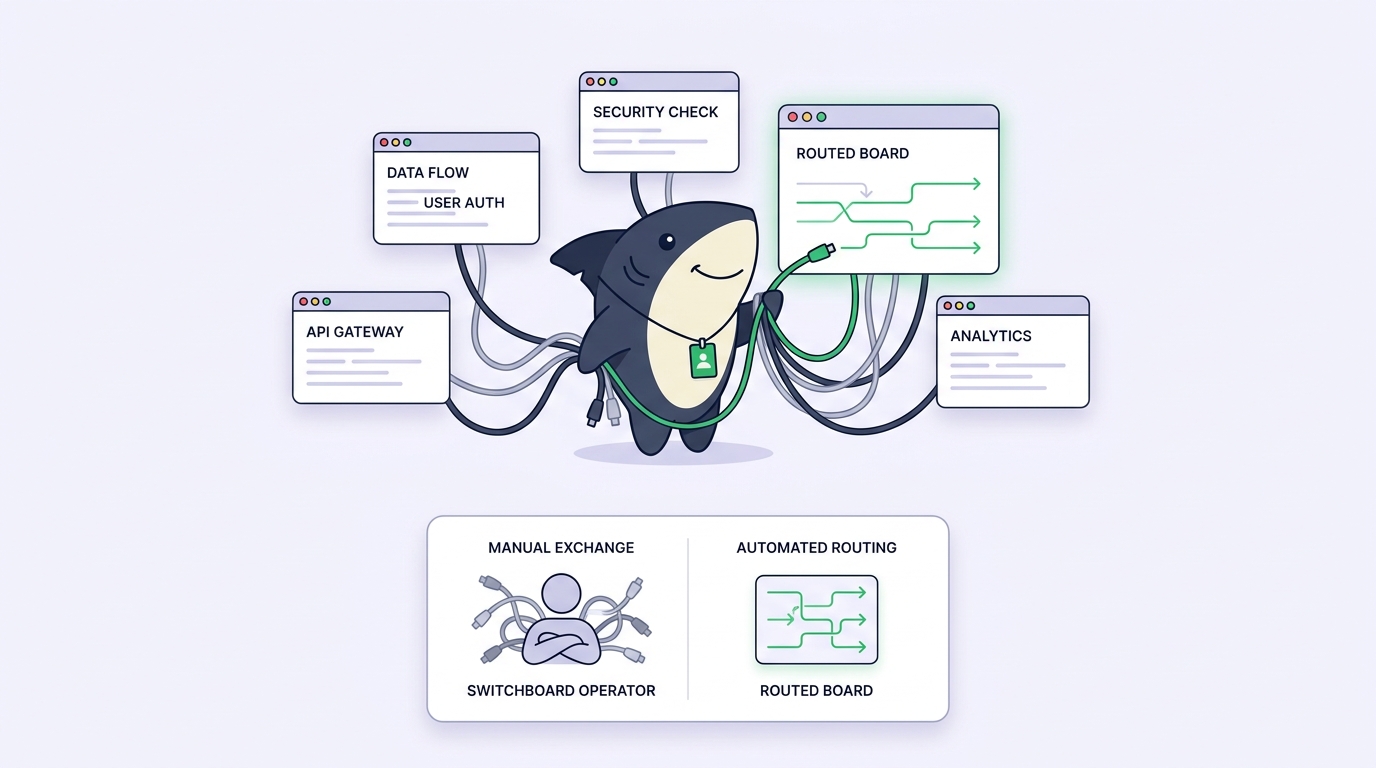
Too Many Terminals: The Real Cost of Running Coding Agents by Hand
Too many terminals isn't the problem. Running coding agents by hand makes you the router, the memory, and the reviewer. Here's the real cost, and how to remove it.
Sophia Carter
September 17, 2026